Text to Image AI Use Cases: Six Jobs That Begin With No Photo
Text to image AI earns its place when no usable photo exists. Six concrete jobs, the boundaries where generation fails, and the disclosure rules that follow.
Ask a room of marketers what text to image AI is for and you will usually hear a list of styles: photorealistic, anime, watercolor, cinematic. That framing hides the decision that actually matters. Before you write a prompt, ask whether a photograph of the thing you need already exists. When it does, editing that photo generally beats generating a new one. The light matches the set, the product is the real product, and nobody has to wonder what the model invented.
Text to image AI earns its place in a different set of jobs, the ones where there is no source frame to start from. This article sorts six of them by the deliverable each produces and the decision each supports, then marks the places where generation is the wrong answer outright. It is the counterpart to the editing side of the platform: use the text to image AI generator when the picture does not exist, and image to image when it does.
Why the source photo decides the use case
Two questions settle most of this. First, does a usable photograph of the subject exist? Second, will anyone check the image against reality? A generated frame passes casual review and fails a comparison. That is not a flaw to fix with better prompting; it is the nature of a picture that was invented rather than captured.
The commercial pressure is real. In Shopify's merchant survey, content generation is the most common use of AI among merchants already using it, at 69 percent, with marketing second at 38 percent. Image work now sits inside that demand. Generation is fast enough to run as exploration rather than as a rare event, which is exactly why the framing matters: cheap output makes it tempting to generate everything, including the jobs where a photo would have been both faster and more accurate.
Use case 1: Concept rounds before a shoot is booked
The most valuable generation often happens before anyone spends money. A photographer, a set, a model and a location are commitments. Eight generated frames that sketch four directions cost a prompt each and a few minutes of review, and they turn a meeting about taste into a meeting about specific images.
What you are buying is a decision, not an asset. The deliverable is a contact sheet: four directions, two frames each, all at the ratio the final campaign will use. The images themselves are usually thrown away once the direction is chosen. That is the correct outcome. Judge the round on whether the team agrees faster, not on whether the frames are publishable.
Use case 2: Comp images that settle a layout argument
Designers need something in the box before the real asset arrives, otherwise every layout debate is hypothetical. A generated comp fills the image area at the exact crop the page will use, so type, buttons and whitespace can be tested against a real composition instead of a grey rectangle.
The constraint that makes this work is arithmetic, not art. Decide the aspect ratio and the text-safe zone first, then ask for a composition that respects them: a subject placed to one side, calm space where the headline goes, no busy detail behind the button. Generated comps should be labelled as comps in the file name and in the handoff, or someone will eventually ship one by accident.
Use case 3: Editorial illustration for ideas a camera cannot hold
Some subjects cannot be photographed at all. Attention, compounding, signal and noise, the feeling of a backlog: a literal photo of these does not exist, and stock libraries answer with the same handshake and the same lightbulb everyone else uses.
This is generation at its most defensible, because there is no reality to contradict. It also rewards a different kind of prompt. Instead of describing a scene, describe the relationship you want visible: one small object carrying weight, three paths converging, a shape that repeats and grows. Ask for a flat, quiet treatment rather than a photoreal one, and keep the palette to three or four tones so the illustration reads at thumbnail size.
Use case 4: Campaign directions for a seasonal reset
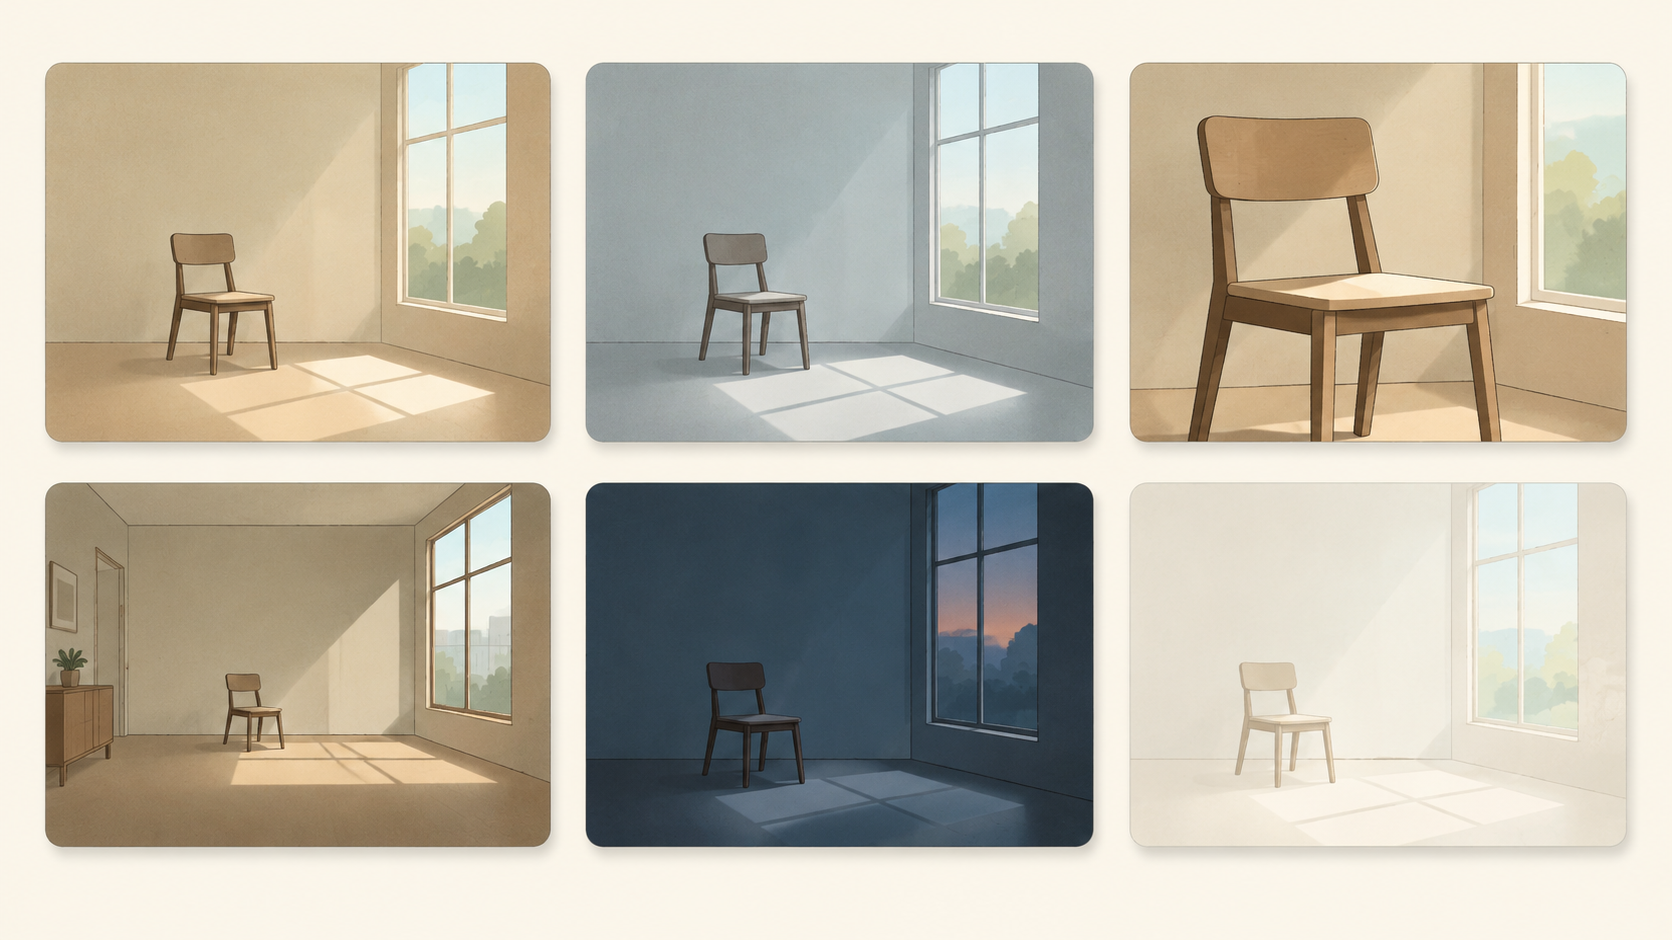
A season or a new market is a natural moment to test a look before commissioning it. Generated frames let a team compare a warm sand palette against a cool grey one, or a close crop against a wide room, using the same subject so the comparison is fair.
Run these as pairs, never as a wall. Two frames that differ in one variable produce a decision; twelve frames produce a debate. Keep the subject and composition identical and change only the light or the palette, then note which pairing the team chose and why. That note is the reusable asset, more than any single image.
Use case 5: Backgrounds, textures, and pattern assets at volume
Backgrounds are the least glamorous and most reliable text to image AI job. A paper grain, a soft gradient, a repeating geometric field, a blurred interior to sit behind a product cutout: none of these has a subject that can be wrong, and all of them are needed in quantity across a campaign.
Two practical rules. Ask for a texture in flat terms with the light direction and colour stated, because vague mood words produce inconsistent results across a set. And treat seamlessness as unproven until you tile it: place four copies in a grid at final size and look for the joint. A pattern that repeats visibly is a pattern you cannot use behind type.
Use case 6: Explainer visuals for decks, docs, and onboarding
Internal material needs clarity, not accuracy about the physical world. A generated metaphor for what a feature does, or what a process looks like from the customer's side, can carry an explanation that a screenshot cannot. Because the audience is colleagues rather than buyers, the review bar is about comprehension, and the image never faces a claim.
Keep these deliberately plain: one concept, one visual relationship, generous empty space for the caption you will add in the slide. Generated explainers age badly when they try to look like product UI, so ask for an abstract diagram, never a fake interface.
Where text to image AI is the wrong tool
Generation fails predictably in four situations, and recognising them early saves a week.
Anything that must match a real object: a product, its packaging, its label, its exact colour, its model number. A generated frame will reproduce the shape approximately and the text badly. Anything that must show a real person, or a person who could be mistaken for one, including testimonials and before-and-after imagery. Anything carrying a regulated claim, where an invented detail becomes a compliance problem. And anything that will be compared side by side with the real thing, in a listing, a review or a support thread.
In those cases the route is a photo, a render, or an edit of an asset you already own. A prompt cannot supply evidence.
One brief that scopes any of the six
Every use case above collapses into the same five-line brief, and writing it takes less time than a single retry.
Line one: the job. What decision does this image support, and who makes it? Line two: the destination and its crop, including the text-safe area. Line three: the subject, context and style, the three-part structure Google's own image prompt guide recommends as a starting point. Line four: the constraints, stated as prohibitions, such as no text, no logos, no hands, no brand marks. Line five: what happens next, meaning whether the frame stays internal or can ever be published.
If line five says internal only, you have removed most of the risk in one sentence. If it says published, the next section applies.
Disclosure duties that follow the image out the door
Generated images increasingly carry obligations that travel with them. Under Article 50 of the EU AI Act, providers of systems that generate synthetic image content must ensure outputs are marked in a machine-readable format and are detectable as artificially generated, an obligation that applies from 2 August 2026 with an exception for assistive standard editing. On the advertising side, California's SB 1050, signed in September 2026 and effective 1 January 2027, requires a clear and conspicuous disclosure when an advertisement prominently features a synthetic performer, using wording substantially similar to "this performance features a synthetic performer" or "no human performer is depicted". New York's comparable requirement has been in effect since June 2026.
The operational lesson is unglamorous. Keep a record of which published assets were generated, who reviewed them and where they ran. Prefer scenes without synthetic humans unless you are prepared to disclose, and prefer real photography when a human presence is the point. Disclosure is cheap at the start of a campaign and expensive after a complaint.
Pick the job where no photo exists
The test for the next image you need is one sentence long: if a photograph exists that could do this job, edit that photograph instead. Text to image AI is the right call for concept rounds, comps, illustration of abstract ideas, seasonal directions, backgrounds and internal explainers, and the wrong call wherever someone will compare the result with reality.
Choose one of the six jobs this week and run it as a single round with a written brief. Keep the frames you rejected next to the one you used, because the rejected set is what tells you which line of the brief was doing the work. That record is worth more than the images; the next round starts from it instead of from a blank prompt.